The system design primer gives engineers a clear path to build scalable systems. It lays out core rules, common patterns, and step-by-step methods. The primer starts with principles that reduce risk. It then shows how to break problems into services and data flows. It ends with pattern guidance engineers can apply on real projects. This article expands those sections with concrete design checks, common pitfalls, and practical guidance teams can apply from concept to operation.
Key Takeaways
- The system design primer guides engineers to build scalable systems by emphasizing core principles like scalability, resilience, clear interfaces, consistency, and observability.
- Data management is crucial; teams must carefully design storage, data flow, and backup strategies while balancing latency, consistency, cost, and performance.
- Automation of testing, deployment, and recovery with capacity and chaos tests ensures system reliability and safe API versioning enables smooth updates.
- A step-by-step design approach includes defining goals, sketching user flows, selecting storage, designing services, adding caching and message queues, and planning for failure scenarios.
- Common system design patterns such as load balancers, caches, message queues, and sharded databases help tackle scaling, latency, and availability challenges effectively.
- Practical rules like starting simple, measuring performance before optimizing, making small reversible changes, and documenting assumptions ensure maintainable and user-focused system design.
Core Principles Of Modern System Design
The system design primer lists a few core principles that every engineer should know. First, the primer states that systems must scale. Teams must design components that handle growth in traffic and data. Second, the primer requires resilience. Engineers must isolate failures and recover fast. Third, the primer favors clear interfaces. Services must expose simple APIs and clear contracts. Fourth, the primer recommends measured consistency. The team must pick a consistency model that matches the user need. Fifth, the primer stresses observability. Engineers must add logs, metrics, and traces to see system health.
To operationalize these principles the primer recommends concrete checks and artifacts: capacity targets per API, SLA/SLO definitions aligned to business goals, a dependency map that shows synchronous calls and latency impact, and a rollback plan for each deployment. It emphasizes that design is not complete until teams can answer: how will we detect, debug, and remediate a production failure within agreed timelines?
The system design primer treats data as a first-class concern. Teams must design how to store, move, and back up data. They must decide when to normalize and when to denormalize. The primer shows trade-offs between latency and consistency. The primer shows trade-offs between cost and performance. Teams must quantify those trade-offs with simple metrics.
Practical data guidance in the primer includes a checklist for storage decisions (access patterns, write volume, query complexity, and retention), recommended backup and restore exercises, and rules for schema migration (backward-compatible changes, feature flags, and read/write path testing). It also highlights data ownership—clear owners who can answer questions about retention, privacy, and recovery for each data set.
The system design primer asserts that automation matters. Teams must automate testing, deployment, and recovery steps. The primer asks teams to add capacity tests and chaos tests. The primer asks teams to run load tests before production deployment. The primer also asks teams to use versioning for APIs. Versioning helps teams deploy changes safely.
Automation examples in the primer include CI pipelines with unit, integration, and contract tests, canary or phased rollouts with automated health checks, and automated post-deploy validation that verifies key flows. For resilience, the primer suggests regularly scheduled chaos experiments and capacity exercises to validate autoscaling, throttling behavior, and graceful degradation under partial failure.
The system design primer highlights team boundaries. Teams must own services end-to-end. The primer suggests that ownership reduces friction. It recommends small, cross-functional teams that can change code and run services. The primer also recommends simple governance to avoid duplication and maintain security.
On organization and process, the primer recommends mapping service ownership to deployment and runbook responsibilities: who owns incident response, who approves schema changes, and who is accountable for capacity planning. It encourages lightweight governance—shared libraries, API review checklists, and a catalog of services—to reduce reinvention while preserving team autonomy.
A Step-By-Step Approach To Designing Real-World Systems
The system design primer gives a clear sequence of steps to follow. Step one: define goals. The team lists capacity targets, latency targets, and cost targets. Step two: sketch user flows. The team maps requests, data writes, and external calls. Step three: pick storage. The primer guides the team to choose SQL, NoSQL, or object storage based on read and write patterns. Step four: design services. The team divides the system into bounded services with clear APIs. Step five: add caching and message queues where they reduce latency or smooth peaks. Step six: design for failure by adding retries, timeouts, and graceful degradation.
Each step has practical checkpoints in the primer. For goals: define success metrics and an SLO with alert thresholds. For user flows: capture critical paths and measure expected QPS and payload sizes. For storage: document access patterns, expected growth rates, and backup windows. For services: define API contracts, idempotency rules, and client-side expectations. For caching and queues: decide eviction policies, cache warming strategies, and dead-letter handling. For failure design: create runbooks for the most likely failure modes and ensure automated recovery where possible.
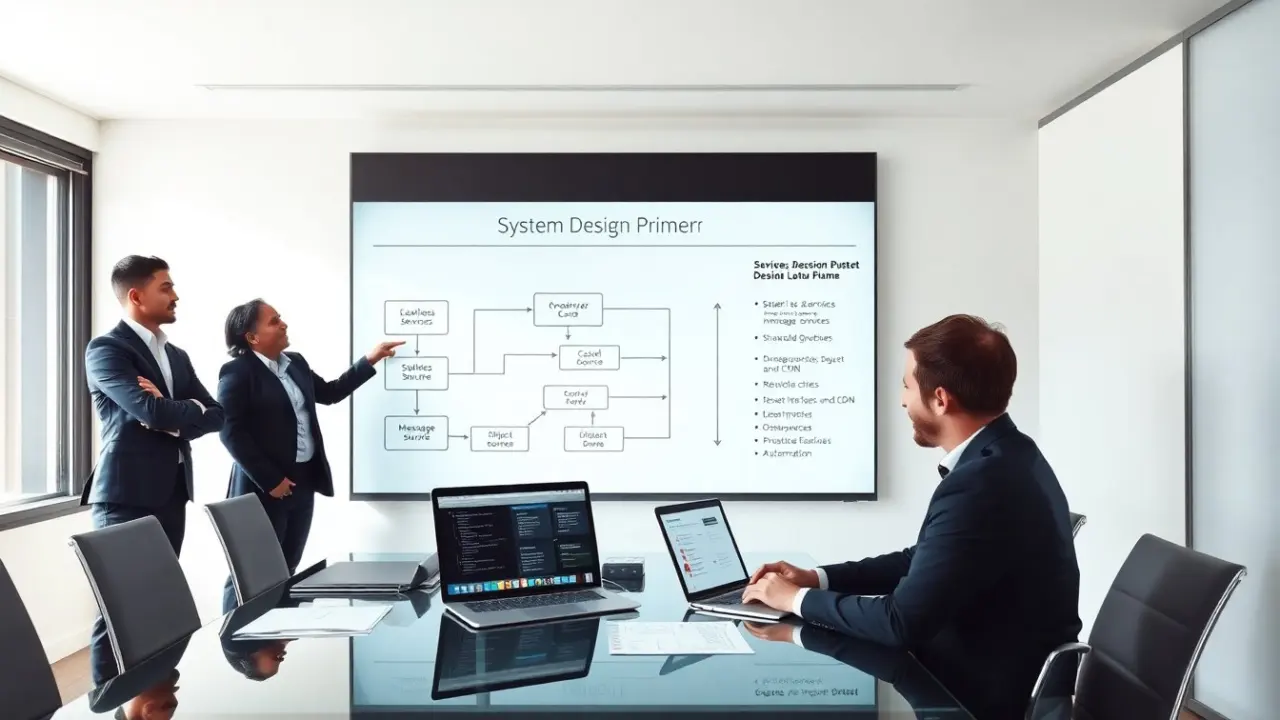
The system design primer asks teams to make simple diagrams. Engineers should show components, data flows, and failure paths. The primer suggests annotating diagrams with expected load and data sizes. The team should pick metrics to monitor for each component. The primer lists common metrics: request rate, error rate, p95 latency, queue depth, and disk usage. The primer asks teams to set alerts on those metrics.
Beyond diagrams, the primer prescribes a minimal deliverable for each design: a one-page summary that includes goals, architecture diagram, key data models, expected bottlenecks, testing plan, and rollback criteria. This one-pager is intended to be a living document updated through prototyping and early production telemetry.
The system design primer recommends iterative design. The team should build a simple prototype, measure it, and improve it. The primer favors small changes with measurable impact. The team should document decisions and trade-offs in a single page. The primer says that clear decision notes help future engineers understand why the system works as it does.
To support iteration, the primer suggests an experiment-first mindset: implement the most uncertain component as a spike, collect metrics from realistic load tests, and use those results to choose between alternatives. It encourages time-boxed experiments and a definition of success for each spike so teams can stop work that does not meet goals quickly.
The system design primer also covers security and compliance. The team must limit access, encrypt data in transit and at rest, and rotate keys. The primer advises simple threat models and threat mitigation steps. The team should include security tests in the pipeline.
Security guidance in the primer includes threat modeling for sensitive flows, a minimum set of controls (authentication, authorization, encryption, auditing), and a plan for regular dependency and vulnerability scans. The primer also emphasizes privacy considerations: minimize data collected, document retention policies, and ensure regulatory controls are reflected in design and runbooks.
Common Patterns, Trade-Offs, And When To Use Them
The system design primer lists common patterns and shows when to use them. Pattern one: load balancer plus stateless service. Use this pattern when the team needs simple scaling and fast recovery. Pattern two: cache in front of database. Use this pattern when reads dominate and latency matters. Pattern three: message queue between services. Use this pattern when the team needs to decouple work and handle bursts. Pattern four: sharded database. Use this pattern when a single database cannot handle the write volume. Pattern five: materialized views. Use this pattern when read queries require complex joins and fast answers.
For each pattern the primer explains typical failure modes and operational considerations. For stateless services behind a load balancer: plan for session management and sticky sessions only when necessary, and instrument connection and instance churn. For caches: define cache miss handling, expiration strategy, and cache invalidation paths. For queues: consider back-pressure, consumer lag monitoring, and replay strategies. For sharding: document shard key selection, rebalancing procedures, and cross-shard transaction handling.
The system design primer explains key trade-offs. Teams must trade consistency for availability when they need low latency across regions. Teams must trade cost for speed when they pick higher-tier instances or more replicas. The primer asks teams to measure the break-even point for each trade.
It also provides guidance to choose between alternatives: prefer eventual consistency for high-throughput analytics pipelines, prefer strong consistency for financial or inventory-critical operations, and use hybrid approaches (read replicas with leader-writes) when different parts of the system have different consistency requirements. The primer encourages teams to capture the chosen trade-offs in design documents and to validate them through tests and production telemetry.
The system design primer gives short examples to clarify choices. Example: a video service uses object storage for blobs, a CDN for delivery, and a SQL store for metadata. That design reduces cost and improves delivery speed. Example: a billing system uses strong consistency and two-phase commit to avoid double charges. That design increases latency but ensures correctness. Example: an event pipeline uses sharding and parallel consumers to scale processing. That design improves throughput at the cost of added operational work.
Finally, the system design primer ends with practical rules. Rule one: start simple. Rule two: measure before optimizing. Rule three: prefer small, reversible changes. Rule four: document assumptions. These rules help teams deliver systems that match user needs while keeping operational burden manageable. Following the primer helps teams move from theory to repeatable practices that are useful across product domains and organizational sizes.